RACE model for ChatGPT prompts: the template with examples
The RACE model as a prompt template: Role, Action, Context and Execute (or Expectation), with filled-in examples per marketing task and the pitfalls

Summary
- RACE is a prompt template in 4 fixed blocks: Role, Action, Context and Execute, written in that order in a single prompt
- The oldest dated source is Trust Insights (first mention July 2023, Execute spelled out from September 2023); Expectation appeared in August 2023 and Examples later, both without a fixed source, and there is no official definition
- Mind the name clash: in marketing, RACE usually means Reach, Act, Convert, Engage, a planning model that has nothing to do with prompts
- A role steers tone and behaviour but does not make answers more accurate: research by Wharton and by Zheng and colleagues found no gain in factual accuracy
- Google and Anthropic recommend examples by default, Anthropic 3 to 5 per prompt: put them in a separate block after Execute
- Copy-ready templates per marketing task, plus a way of working for teams: standing role and context in project instructions, the task in the prompt
The RACE model is a fixed structure for building a ChatGPT prompt in 4 blocks: Role, Action, Context and Execute. Look it up and you quickly run into two confusions. In marketing, RACE usually stands for a planning model that has nothing to do with prompts, and within the prompting world three readings of the last letter circulate. We set out the origins honestly and then give you what you came for: a template to copy, filled in for the marketing tasks that come back every week at an SME, with the pitfalls and a way of working for your team. We do not repeat the basics of a good prompt here. Those are in our guide to writing better prompts, and the techniques beyond them in advanced prompt engineering.
What does the RACE model stand for in ChatGPT prompts?
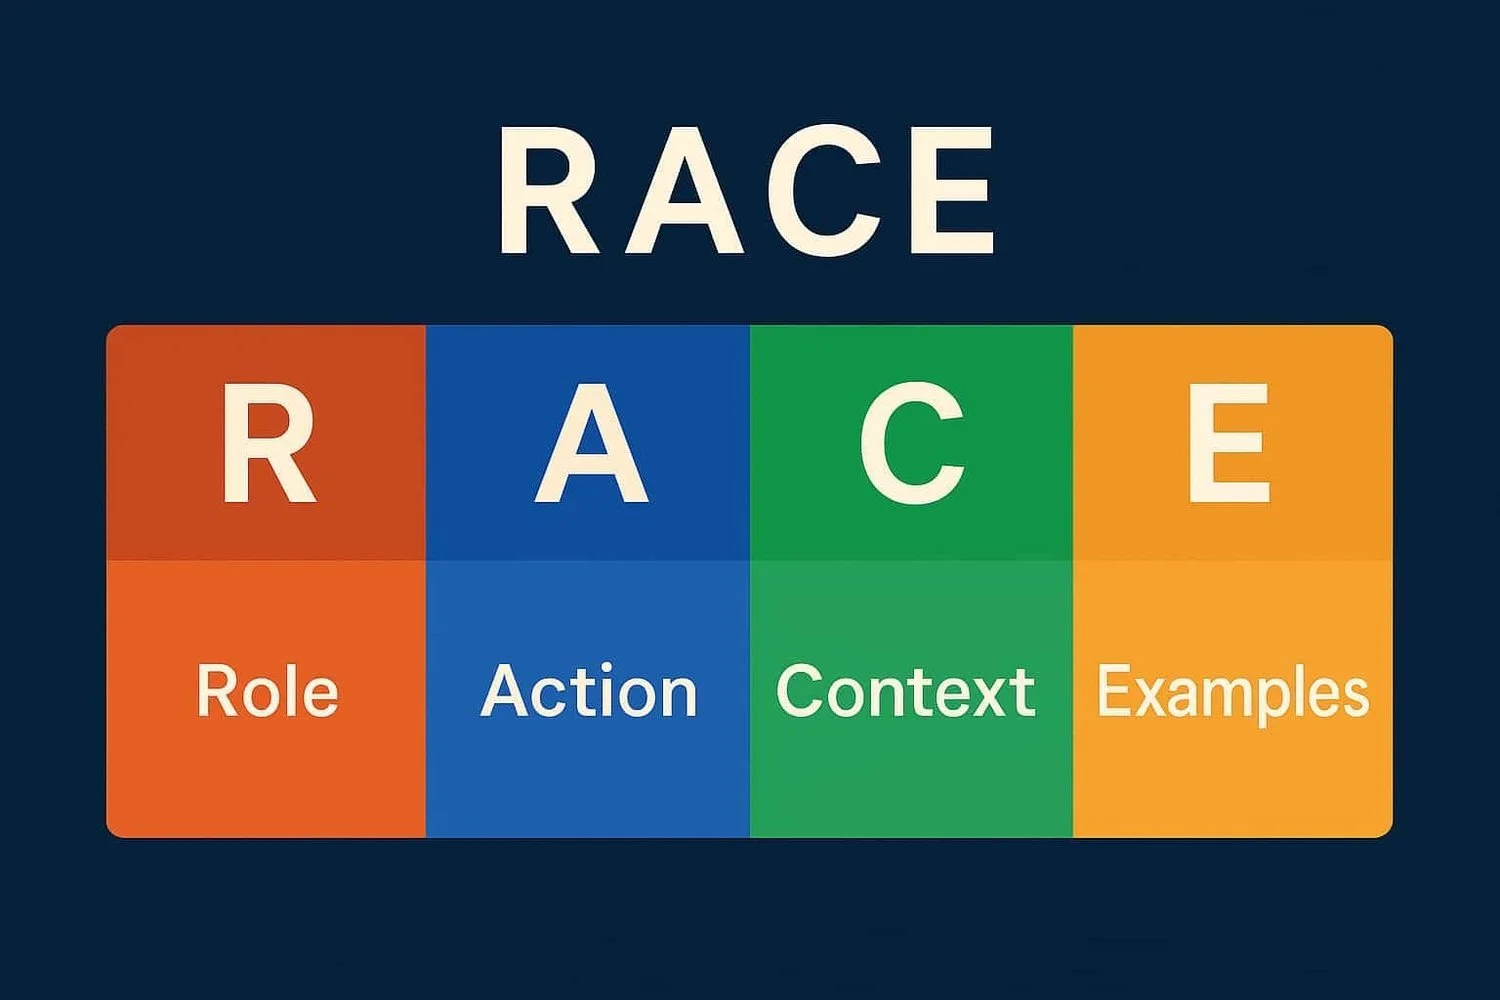
RACE stands for Role, Action, Context and Execute: the role the AI takes on, the task you ask for, what the model needs to know about your situation and the form the answer should take. You write those 4 blocks underneath each other in one prompt. The framework comes from the practice of an analytics and AI consultancy and has no academic origin.
| Block | Question you answer | Example line |
|---|---|---|
| Role | Who should the AI be? | “You are a copywriter with experience in B2B software.” |
| Action | What needs to happen? | “Write a follow-up email for prospects who did not reply.” |
| Context | What does it need to know to do it well? | “Audience, product, tone of voice, what has already been sent.” |
| Execute | What should the answer look like? | “Maximum 130 words of flowing text, with 3 subject lines.” |
The oldest dated source we found is Trust Insights, the Boston consultancy of Christopher Penn and Katie Robbert. Their newsletter of 12 July 2023 refers to “the RACE prompt structure we recommend”, and on 6 September 2023 it spells it out as Role, Action, Context, Execute. Trust Insights presents RACE as its own framework, based on the documentation of the companies behind the language models. That the consultancy invented it remains their own claim: it is the earliest dating we found, not conclusive proof that nothing older exists.
Trust Insights has since released a more extensive successor, RAPPEL (October 2024), and a version for reasoning models (April 2025). They do not discard the original themselves:
“So, the original RACE framework was role, action, context, execute, which, by the way, still works, to be clear.”
— Christopher S. Penn, co-founder of Trust Insights, on the In-Ear Insights podcast (October 2024)
That makes RACE a good framework to start with. ClickForest uses templates like this in its AI training for SMEs in Flanders, because 4 blocks are easy to remember and quickly bring a team to the same level.
Mind the name. Anyone talking about the RACE model in a marketing context often means the Smart Insights planning model: Reach, Act, Convert, Engage, a breakdown of the customer journey by Dave Chaffey that has nothing to do with AI prompts. Same 4 letters, different field. Here we consistently mean the prompt framework; the planning model belongs in a conversation about online marketing and channel strategy.
What does the E in RACE stand for?
The E stands for Execute at Trust Insights, the oldest source that mentions RACE, and for Expectation in the version you see most often in search results and course material. A third variant uses Examples. All three fill the same closing block: what you expect from the answer and what it should look like. There is no official definition that settles the matter.
This is how the variants diverged:
- Execute (September 2023): the version of Trust Insights, the consultancy that already mentioned RACE in July 2023. The consultancy itself is not consistent. It also writes “Execution”, and in a newsletter from April 2025 it describes that E as “tell the model what you expect for outcomes”, which comes close to Expectation. In 2025, Ayse Ozturk summed up Execute as “Specify the output style”.
- Expectation (August 2023): the earliest place we found it is a LinkedIn article by Edi Hezri Hairi of 3 August 2023 listing 9 prompt frameworks, without crediting a source for this one. Under Expectation it says: “Describe the expected outcome.” That list has been copied widely. Whether Expectation descends from Trust Insights or arose independently cannot be established. In 2025, Fabio Vivas gave it a sentence template: “As a [Role], [Action] considering [Context]. I expect [Expectation].”
- Examples (2024): Side School, among others, uses the closing block for “good examples of structures we would like to reproduce”. We could not trace where this variant comes from.
In the template we stick with Execute, because an instruction about form and format is needed in almost every task. If you searched for “role action context expectation”, you lose nothing with this template: describe the result you expect in the closing block together with the form, and you have the same prompt. We add examples as a separate block after Execute, so anyone who knows the Examples variant gets what they need too. How that works is covered further down.
What does a RACE prompt actually look like?
As 4 labelled blocks underneath each other, each starting with the name of the component. The labels force you to skip nothing and make the prompt reusable, because you only replace the fill-in fields. They also help the model: according to OpenAI, headings and lists mark off the different parts of a prompt. This is the empty template:
Role: You are a [job title or expertise] with experience in [sector or domain].
Action: [Verb] [what exactly] for [whom].
Context: We are [company or product]. Audience: [description].
         Tone of voice: [description]. What you need to know: [facts, figures,
         constraints, what has already happened, why this task matters].
Execute: [Length and language]. [Structure: paragraphs, heading, table, number of variants].
         [How it should sound, in positive terms].
         Also avoid: [specific words or elements that must not appear].
Note the order in the Execute block. First you describe what you do want, and only then what must stay out. Anthropic recommends this explicitly: “Tell Claude what to do instead of what not to do”. A model knows better what to do with “write in flowing paragraphs” than with “do not use bullet points”.
And this is what it looks like filled in for a concrete task:
Role: You are a copywriter with experience in B2B software for manufacturers.
Action: Write a follow-up email to prospects who attended our webinar last month
        but have not booked a demo yet.
Context: We sell planning software to manufacturers with 50 to 250 employees.
         The reader is a production manager, not an IT specialist.
         Their biggest frustration is planning in spreadsheets and reshuffling
         every week. The webinar covered planning mistakes that cost money.
         This email should reopen the conversation, not sell yet.
         Tone of voice: matter-of-fact and concrete, like a colleague in the sector.
Execute: Maximum 130 words, in English, in short paragraphs of flowing
         text, with 3 subject lines to choose from. Mention one concrete
         planning problem from the webinar and close with one question
         that can be answered with yes or no.
         Also avoid: the word "solution" and a list of features.
The difference with “write a follow-up email about our webinar” is big. With that short request, the model can only write an average email; the filled-in version gives it enough to make something that sounds like your company. If you work in Claude, you can also mark off the blocks with XML tags such as <context> and </context>, which Anthropic recommends for keeping instructions, context and examples apart. The RACE labels do the same in plain language.
Which RACE templates can you copy straight away?
Below are 6 templates for recurring marketing tasks: product description, LinkedIn post, follow-up email, ad copy, review analysis and blog brief. Replace the brackets with your own details and leave the labels in place. They are deliberately compact. Your Context block may well end up 3 times as long, because that is where quality comes from.
| Task | RACE template |
|---|---|
| Product description | Role: copywriter for an online shop in [sector]. Action: write a product description for [product] aimed at [audience]. Context: [what the product does], [why customers hesitate], tone of voice [description]. Execute: 120 words, opening line plus 3 concrete benefits plus closing line, in a matter-of-fact tone that lets the facts speak. |
| LinkedIn post | Role: content lead at [company]. Action: write 3 variants of a post about [topic]. Context: audience [role and sector], what we have to say about it: [position or experience]. Execute: max 120 words per variant, each with a different opening (question, figure, anecdote), ending with a question to the reader. Also avoid hashtags. |
| Follow-up email | Role: [your job title] at [company]. Action: write a follow-up email to [type of contact] who [situation]. Context: earlier contact moments [description], their objection is probably [objection], tone of voice [description]. Execute: max 130 words, first person, 3 subject lines, close with one question. |
| Ad copy | Role: performance copywriter. Action: write 5 ad headlines and 2 descriptions for [campaign]. Context: offer [description], audience [description], what sets us apart: [point]. Execute: headlines max 30 characters, descriptions max 90 characters, in English, each headline with a different benefit. |
| Review analysis | Role: marketing analyst. Action: analyse the customer reviews below and pull out the recurring patterns. Context: we are a [type of business], we want to know [question]. Reviews: [paste here]. Execute: 5 patterns in a table, each with a quote from the data and one action we can take. |
| Blog brief | Role: content strategist. Action: create an article brief about [topic]. Context: audience [description], search intent [informational or commercial], what we have already published: [links]. Execute: working title, 6 to 8 H2s phrased as questions, 2 sentences of direction per H2, plus 5 FAQ questions. |
For the strategy behind the LinkedIn post and the ad copy, see our articles on LinkedIn marketing for B2B leads and optimising Google Ads.
How do you sharpen Role, Action, Context and Execute?
Each block has its own rule of thumb: keep the role credible, make the action measurable, fill in the context until a new colleague could get going with it, and describe the form so that you can tick off the result. Most disappointing output traces back to one block filled in too thinly, and that is nearly always Context.
Role: tone and angle
Pick a role that matches the perspective you want (“copywriter for online shops in the garden sector”), and do not count on it for knowledge. Zheng and colleagues tested 162 roles on 2,410 factual questions across 4 model families and found that a persona in the system prompt does not improve performance. Wharton Generative AI Labs confirmed this in December 2025 on 6 more recent models from OpenAI and Google: an expert role did not make the answers more accurate. A role from the wrong field even made one of the Gemini models regularly refuse to answer.
“For factual work, it doesn’t really matter, so don’t overcomplicate it”
— Lennart Meincke, research fellow at the Mack Institute for Innovation Management at Wharton, in Knowledge at Wharton (April 2026)
What a role does do is steer behaviour and tone. Anthropic writes: “Setting a role in the system prompt focuses Claude’s behavior and tone for your use case.” The Wharton researchers also see value in a role for setting perspective and tone. So use Role for voice and angle, and put the knowledge the answer needs into Context yourself. A role that comes back in every task belongs in the system prompt, where Anthropic, Google and OpenAI all recommend it, or in your assistant’s project instructions. One caveat: both studies tested factual questions. What a role does for a marketing text has not been researched.
Action: one task, one verb
One task per prompt, with a verb up front. An email, 3 posts and an analysis in one prompt rarely produce 3 usable results. Splitting is nearly always faster than reworking. Make the task measurable too: “write 5 headlines” can be checked, “write something catchy” cannot.
Context: the block that makes the difference
Audience, offer, tone of voice, what has already happened, what is off limits, and why the task matters. A good test: could a freelancer start from this brief without calling you back? Anthropic uses the same image: it describes Claude as a brilliant but new employee who does not yet know your norms and ways of working.
Anthropic also recommends giving the reason behind an instruction, because the model then understands your goal better. That is why the template puts “why this task matters” under Context. Google says the same about context: “This contextual information helps the model understand the constraints and details of what you’re asking for it to do.”
Execute: what you want first
Length, language, structure, number of variants and tone, phrased as what you want to see. Put prohibitions after that as an addition, for a specific word or element that really must stay out. The more precise the block, the easier it is to tick off the result without discussion.
And with reasoning models?
Models that think before they answer call for a slightly different approach. OpenAI writes: “reasoning models will provide better results on tasks with only high-level guidance. This differs from GPT models, which benefit from very precise instructions.” Trust Insights adapted RACE to this in April 2025: let the model choose a role itself, let it think about what it is doing and why, and give it thorough source material as context. Their summary: “We still have to tell them what to do and why to do it, but we now leave how to do it up to them.” With a reasoning model, you keep Action and Context just as sharp, and Execute can be more about the goal than about every detail of the form.
When should you add examples to your RACE prompt?
For any task whose tone or form is hard to capture in words, and according to Google, almost always. Two paragraphs you like say more than 10 adjectives. According to Anthropic, 3 to 5 examples give the best result; with too many, Google says, the model starts following them too literally. Put them in a separate block after Execute.
“We recommend to always include few-shot examples in your prompts. Prompts without few-shot examples are likely to be less effective.”
— Google, Gemini API documentation Prompt design strategies (consulted October 2026)
That technique is called few-shot prompting, and it is exactly what the Examples variant of RACE refers to. It pays off above all for tone of voice, for a fixed format that is hard to describe (a product sheet, a reporting block) and for classification tasks, where one example per category puts the model on the right track immediately. Choose examples that differ from each other: OpenAI recommends showing “a diverse range of possible inputs with the desired outputs”. That way the model picks up the common pattern.
Mark off the block clearly, so the model knows where the examples begin and end:
Examples:
<example>
[a product description you like]
</example>
<example>
[a second one, for a different type of product]
</example>
Write in the voice and structure of these examples. Do not copy sentences or facts from them.
That last line matters: without it, a model sometimes copies phrasing or product details word for word. The broader set of techniques, from handing over examples to step-by-step reasoning, is covered in our article on prompt engineering. A short definition of the term is in the glossary.
How does RACE compare with CO-STAR, CREATE and RISEN?
Of these 4 frameworks, RACE is the shortest. CO-STAR and CREATE give a block of their own to things RACE folds into Context or Execute, such as audience, tone or examples. We found no source showing that one framework produces better output than another. So choose the framework your team will actually fill in completely.
| Framework | Letters | Origin | What it names separately |
|---|---|---|---|
| RACE | Role, Action, Context, Execute | Trust Insights, dated from July 2023 | The minimum: role, task, context and form |
| CO-STAR | Context, Objective, Style, Tone, Audience, Response | Used by GovTech Singapore in its Prompt Engineering Playbook | Style, tone and audience, each as a block of its own |
| CREATE | Character, Request, Examples, Adjustments, Type of output, Extras | Dave Birss, by his own account shortly after the launch of ChatGPT in November 2022 | Examples and adjustments as a block of their own |
| RISEN | Role, Instructions, Steps, End goal, Narrowing | Attributed to Kyle Balmer; we could not open the original source | The steps, the end goal and the narrowing |
Singapore’s government technology agency writes about CO-STAR: “At GovTech, our officers follow the CO-STAR Framework, featured in our Prompt Engineering Playbook, to craft better prompts.” Dave Birss describes CREATE in his own summary as a framework he developed “Shortly after ChatGPT’s launch in November 2022”.
In practice they sit close together. What CO-STAR puts under Style, Tone and Audience, you write in the Context block in RACE. Use RACE with a separate examples block, as above, and in substance you are close to CREATE.
What usually goes wrong with a RACE prompt?
Rarely the framework itself, nearly always the way it is filled in. The classics are an empty Context block, several tasks in one prompt, an Execute block that only says “professional”, a role treated as a source of knowledge, and a template filled in mechanically without thinking about the task. A quieter mistake: an Execute block that only lists what must stay out.
What helps against that is banal but effective. Treat the first answer as a rough version and steer in a second turn; a 3-turn conversation usually produces better work than one mega-prompt. Check facts, figures and names before publishing, even when the answer reads smoothly, because a language model can make something up with conviction (a hallucination). And save what works straight away, because the prompt you get right today after 4 attempts is gone next week.
You need to worry less about length than is often thought. Current models handle very long instructions, so relevance weighs more than brevity. The limit is noise: do not paste in entire documents when only 3 lines matter. If you want to see how the choice between AI text and your own work plays out in practice, AI copywriting versus human is a useful companion piece.
How do you turn RACE into a standing way of working for your team?
By splitting the template. What stays the same in every task, such as role, tone of voice and audience, you put once in standing instructions. What changes per task, Action and the specific Execute block, stays in the prompt. Also store the best filled-in templates centrally with fill-in fields, so everyone starts at the same level.
In Claude you can do that with projects. Anthropic describes them as “self-contained workspaces with their own chat histories and knowledge bases”, and per project you can set instructions that steer the answers, for example from a specific role. If you work in another assistant, look for the place for standing instructions that come with every chat. If you want to go further, Claude also lets you capture reusable ways of working as skills.
Practically: pick 3 recurring tasks, work out one RACE template per task, test for a week, and sharpen based on what the output structurally misses. Agree on who maintains the library and add one line to each template about when to use it. Review after a month which templates actually get used; those 2 or 3 are your gain, the rest can go. If this grows into workflows you would rather run automatically, marketing automation is the next step, and beyond that AI agents in marketing.
Want your team to master this on your own tasks? ClickForest runs practical AI training for SMEs in Flanders, in which we work out the templates and standing instructions together for the work that comes back every week at your company. See the AI training or get in touch.
What should you remember about the RACE model?
RACE is a memory aid with 4 blocks: Role, Action, Context, Execute. The E has variants, Expectation and Examples, and no official definition, so pick one and stay consistent. The value lies in the discipline the blocks enforce, above all in the Context block, and in examples you add as a separate block. A role mainly steers tone and angle.
Use the framework where it belongs: for recurring tasks you want to standardise. ClickForest helps SMEs in Flanders apply such templates to their own recurring tasks. If you prefer a looser formula, start with writing prompts in 4 steps; if you want to go beyond templates, head to prompt engineering. Which assistant you choose matters less than you might think, though our comparison of AI tools helps you work out what suits which task. And if you want to use AI more broadly than text alone, that starts at AI for growth.
Grow with AI, practically and without unnecessary complexity
Ready to use AI to save time and accelerate your marketing? Discover our AI services
Discuss your challenge directly with Frederiek: Book a free strategy call or send us a message
Prefer email? Send your question to frederiek@clickforest.com or call +32 473 84 66 27
Strategy without action remains theory. Let's take your next step together.
Frequently asked questions
RACE stands for Role, Action, Context and Execute: you give the AI a role, a concrete task, the background of your situation and an instruction about the form of the answer. In other versions the E stands for Expectation (the expected result) or Examples. There is no official definition; all variants fill the same closing block.
No. The Smart Insights RACE model (Reach, Act, Convert, Engage) is a planning model for the customer journey in digital marketing and says nothing about prompts. The RACE in this article is a prompt structure from AI practice, with the same 4 letters and no connection at all.
Hardly at all in substance: Role matches Role, Action matches Goal, Context matches Context and Execute matches Output. RACE is a stricter structure with labelled blocks, handy for reusable templates and team agreements. The formula from the ClickForest basics guide reads more naturally when you want something quickly.
No. For a short question, Action and Context often suffice. The full template pays off once the task recurs, the output has to sound like your brand or several colleagues need to reach the same quality, and then Context is the block you can least afford to skip.
Yes. RACE is a way to order your instruction and works in any assistant that accepts text prompts. For Claude, Anthropic recommends marking off the blocks, for example with XML tags, and OpenAI mentions headings and lists as a way to separate the parts of a prompt.
Yes, with a small adjustment. According to OpenAI, reasoning models work better with high-level instructions, so keep Action and Context sharp and let Execute be more about the goal than about every detail of the form. Trust Insights, the oldest dated source of RACE, says itself that the original framework still works.
Start with 3 recurring tasks, work out one RACE template per task and put the standing parts, such as role and tone of voice, in project instructions. Agree on who maintains the library and review after a month which templates are actually used. ClickForest works those templates out together with your team during a tailored AI training.
Sources and references
RACE as a prompt framework and the variants of the E:
- Trust Insights: Inbox Insights newsletter of 12 July 2023 (earliest mention of RACE we found) · https://www.trustinsights.ai/blog/2023/07/inbox-insights-ai-efficiencies-ripple-effects-chatgpt-code-interpreter/
- Trust Insights: Inbox Insights newsletter of 6 September 2023 (Role, Action, Context, Execute) · https://www.trustinsights.ai/blog/2023/09/inbox-insights-september-6-2023-when-chatgpt-goes-sideways-content-curation-systems/
- Trust Insights (Christopher Penn): Instant Insights on the RACE AI framework (2024) · https://www.trustinsights.ai/insights/instant-insights/instant-insights-trust-insights-race-ai-framework/
- Trust Insights: In-Ear Insights podcast on the RAPPEL framework (October 2024) · https://www.trustinsights.ai/blog/2024/10/in-ear-insights-the-trust-insights-rappel-ai-prompt-framework-explained/
- Trust Insights: Inbox Insights newsletter of 9 April 2025 (RACE for reasoning models) · https://www.trustinsights.ai/blog/2025/04/inbox-insights-april-9-2025-ai-integration-strategy-part-1-ai-prompting-frameworks/
- Edi Hezri Hairi: "9 Frameworks to master ChatGPT Prompt Engineering" (variant with Expectation, 2023) · https://www.linkedin.com/pulse/9-frameworks-master-chatgpt-prompt-engineering-edi-hezri-hairi/
- Fabio Vivas: "RACE framework for prompts" (variant with Expectation, 2025) · https://fvivas.com/en/race-framework-prompts-llm/
- Side School: explanation of RACE (variant with Examples, 2024) · https://www.side.school/en/resources/race
- Dr. Ayse Ozturk: "Another prompting framework: RACE" (2025) · https://drayseozturk.org/2025/02/22/another-prompting-framework-race-role-action-context-execute/
Other prompt frameworks:
- GovTech Singapore: article on prompt engineering with the CO-STAR framework (2025) · https://www.tech.gov.sg/technews/mastering-the-art-of-prompt-engineering-with-empower/
- Dave Birss: summary of Smarter learning with AI (the CREATE framework, pdf) · https://davebirss.com/downloads/smarter_learning_with_AI_summary.pdf
The other RACE model (marketing planning):
- Smart Insights (Dave Chaffey): "The RACE Framework" (Reach, Act, Convert, Engage) · https://www.smartinsights.com/digital-marketing-strategy/race-a-practical-framework-to-improve-your-digital-marketing/
Official prompt documentation:
- Anthropic: "Prompting best practices" · https://platform.claude.com/docs/en/build-with-claude/prompt-engineering/claude-prompting-best-practices
- OpenAI: Prompt engineering guide · https://developers.openai.com/api/docs/guides/prompt-engineering
- Google: "Prompt design strategies" (Gemini API) · https://ai.google.dev/gemini-api/docs/prompting-strategies
- Anthropic: Claude Help Center on projects and project instructions · https://support.claude.com/en/articles/9517075-what-are-projects
Research on roles in prompts:
- Zheng et al.: "When A Helpful Assistant Is Not Really Helpful: Personas in System Prompts Do Not Improve Performances of Large Language Models" (2023, revised 2024) · https://arxiv.org/abs/2311.10054
- Wharton Generative AI Labs: "Playing Pretend: Expert Personas Don't Improve Factual Accuracy" (2025) · https://gail.wharton.upenn.edu/research-and-insights/playing-pretend-expert-personas/
- Knowledge at Wharton: interview with Lennart Meincke on expert roles in prompts (April 2026) · https://knowledge.wharton.upenn.edu/article/why-you-shouldnt-ask-chatbots-to-act-like-an-expert/